
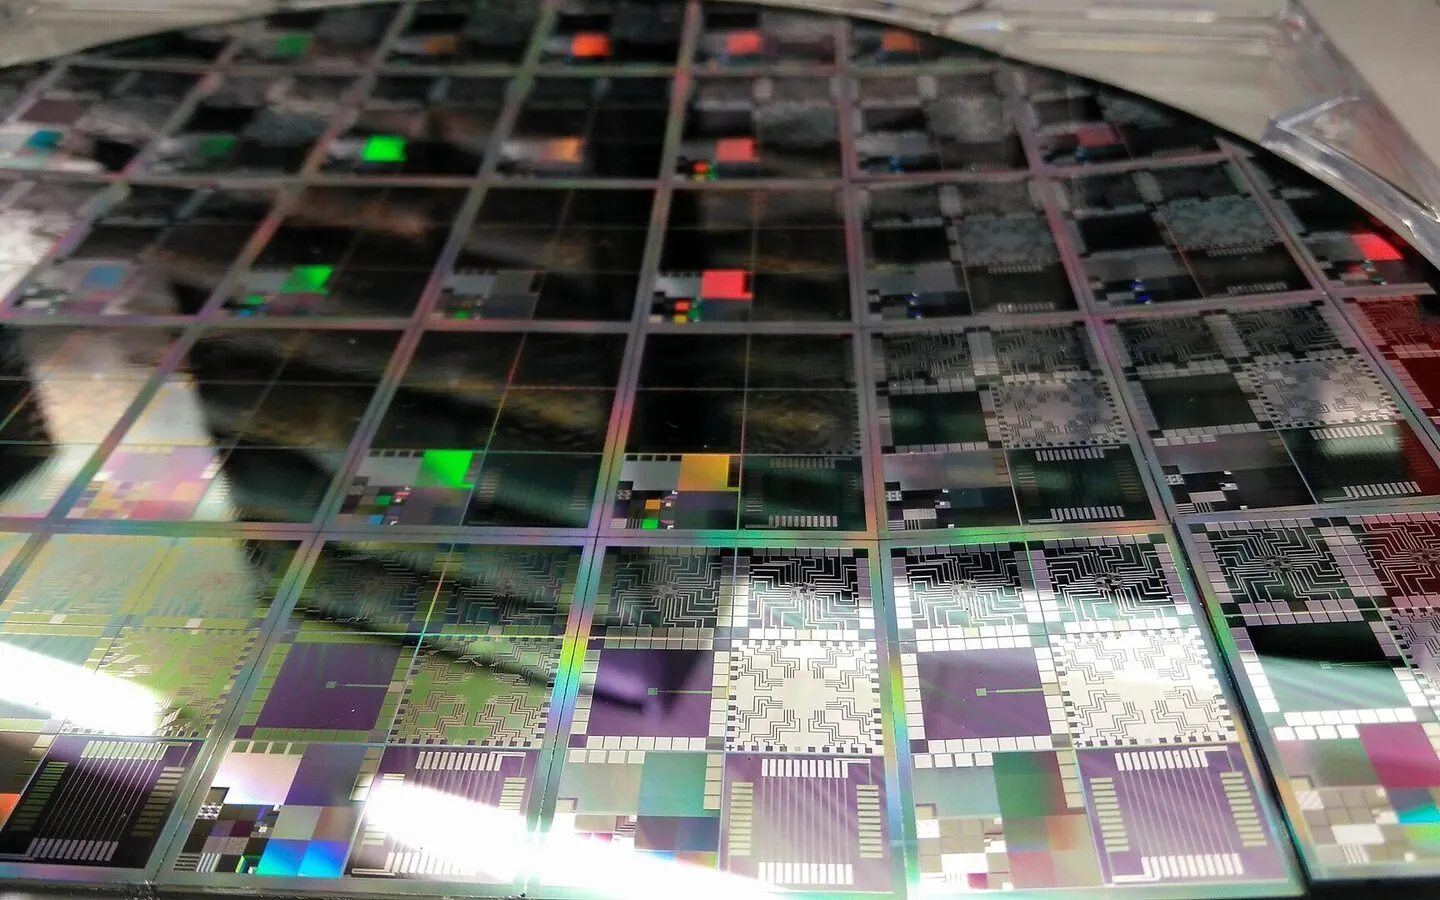
GlobalFoundries and RAAAM Memory Technologies have taped out a Gain-Cell RAM test vehicle on GlobalFoundries’ FDX FD-SOI platform, opening a new phase for a lower-area on-chip memory design. The companies announced the milestone in a September 2 release, describing GCRAM as a possible answer to the memory density and power limits facing edge AI, automotive, and IoT chips.
The result is not a finished processor or a shipping memory product. It is a jointly designed test chip that lets the partners qualify the bitcell on a commercial foundry process. GlobalFoundries describes the underlying FDX FD-SOI platform as an edge-focused technology, while the release says lead customers should receive GCRAM design access in early 2027.
Why embedded memory is becoming a system problem
On-chip memory sits close to the logic that uses it, so it can avoid some of the delay and energy cost of moving data to external memory. That matters more as edge devices analyze richer sensor streams and run larger machine-learning models. GlobalFoundries says on-chip memory can represent the majority of a chip’s silicon area, making density and leakage important design constraints rather than minor implementation details.
RAAAM’s GCRAM changes the memory cell used for that local storage. The companies say their co-designed bitcell uses pushed design rules on FDX technology and achieves a 40% memory-area reduction and up to 60% lower memory power than commodity SRAM. Those are projected results reported by the partners for the joint design, not measurements of a finished commercial product.
The architecture targets a familiar tradeoff. SRAM is fast and easy for a processor to use, but its cell area limits how much cache or working memory designers can fit on a die. A denser replacement could leave room for more local data, or preserve the same capacity while freeing silicon for compute, connectivity, or security features. Lower power at the memory array could also reduce the energy spent keeping data near an accelerator.
That logic connects to our earlier explanation of memory bandwidth as an AI hardware bottleneck. More local capacity does not solve every bandwidth problem, and GCRAM does not remove the need for external DRAM, software optimization, or a suitable interconnect. It could, however, reduce how often a workload has to reach beyond the processor for frequently used data.
A test vehicle, not a product launch
The tape-out is an important manufacturing checkpoint because the design has moved from an IP claim into a fabricated test vehicle. The next questions are electrical validation, yield, reliability, and how much of the projected area and power advantage survives the full memory macro and its support circuitry. The announcement does not provide final silicon measurements or name a commercial chip using the technology.
NXP is evaluating the potential of the joint solution, according to the release. That interest reflects the market GCRAM is aimed at: intelligent edge systems that need more local processing without giving every square millimeter or milliwatt to memory. Similar constraints appear in the local AI hardware choices covered by our NPU, GPU, and CPU guide, where memory behavior can matter as much as compute throughput.
GlobalFoundries and RAAAM say the next commercial step is design access for lead customers in early 2027. Until those customers publish implementation results, the defensible takeaway is narrower: a foundry and an embedded-memory startup have taped out a test vehicle that targets a meaningful edge-AI constraint, with validation still ahead.



